

Introduction
At our company, we run a self-hosted AI platform serving 400 employees. We use MiniMax-M2.5 open model, served through vLLM on NVIDIA H200 GPUs. Our goal was to deploy a high-performance coding assistant capable of handling large developer contexts and prompts frequently exceeding 100K tokens.
Along the way, we achieved a ~2x improvement in generation speed and a ~50% increase in output throughput under concurrent load.
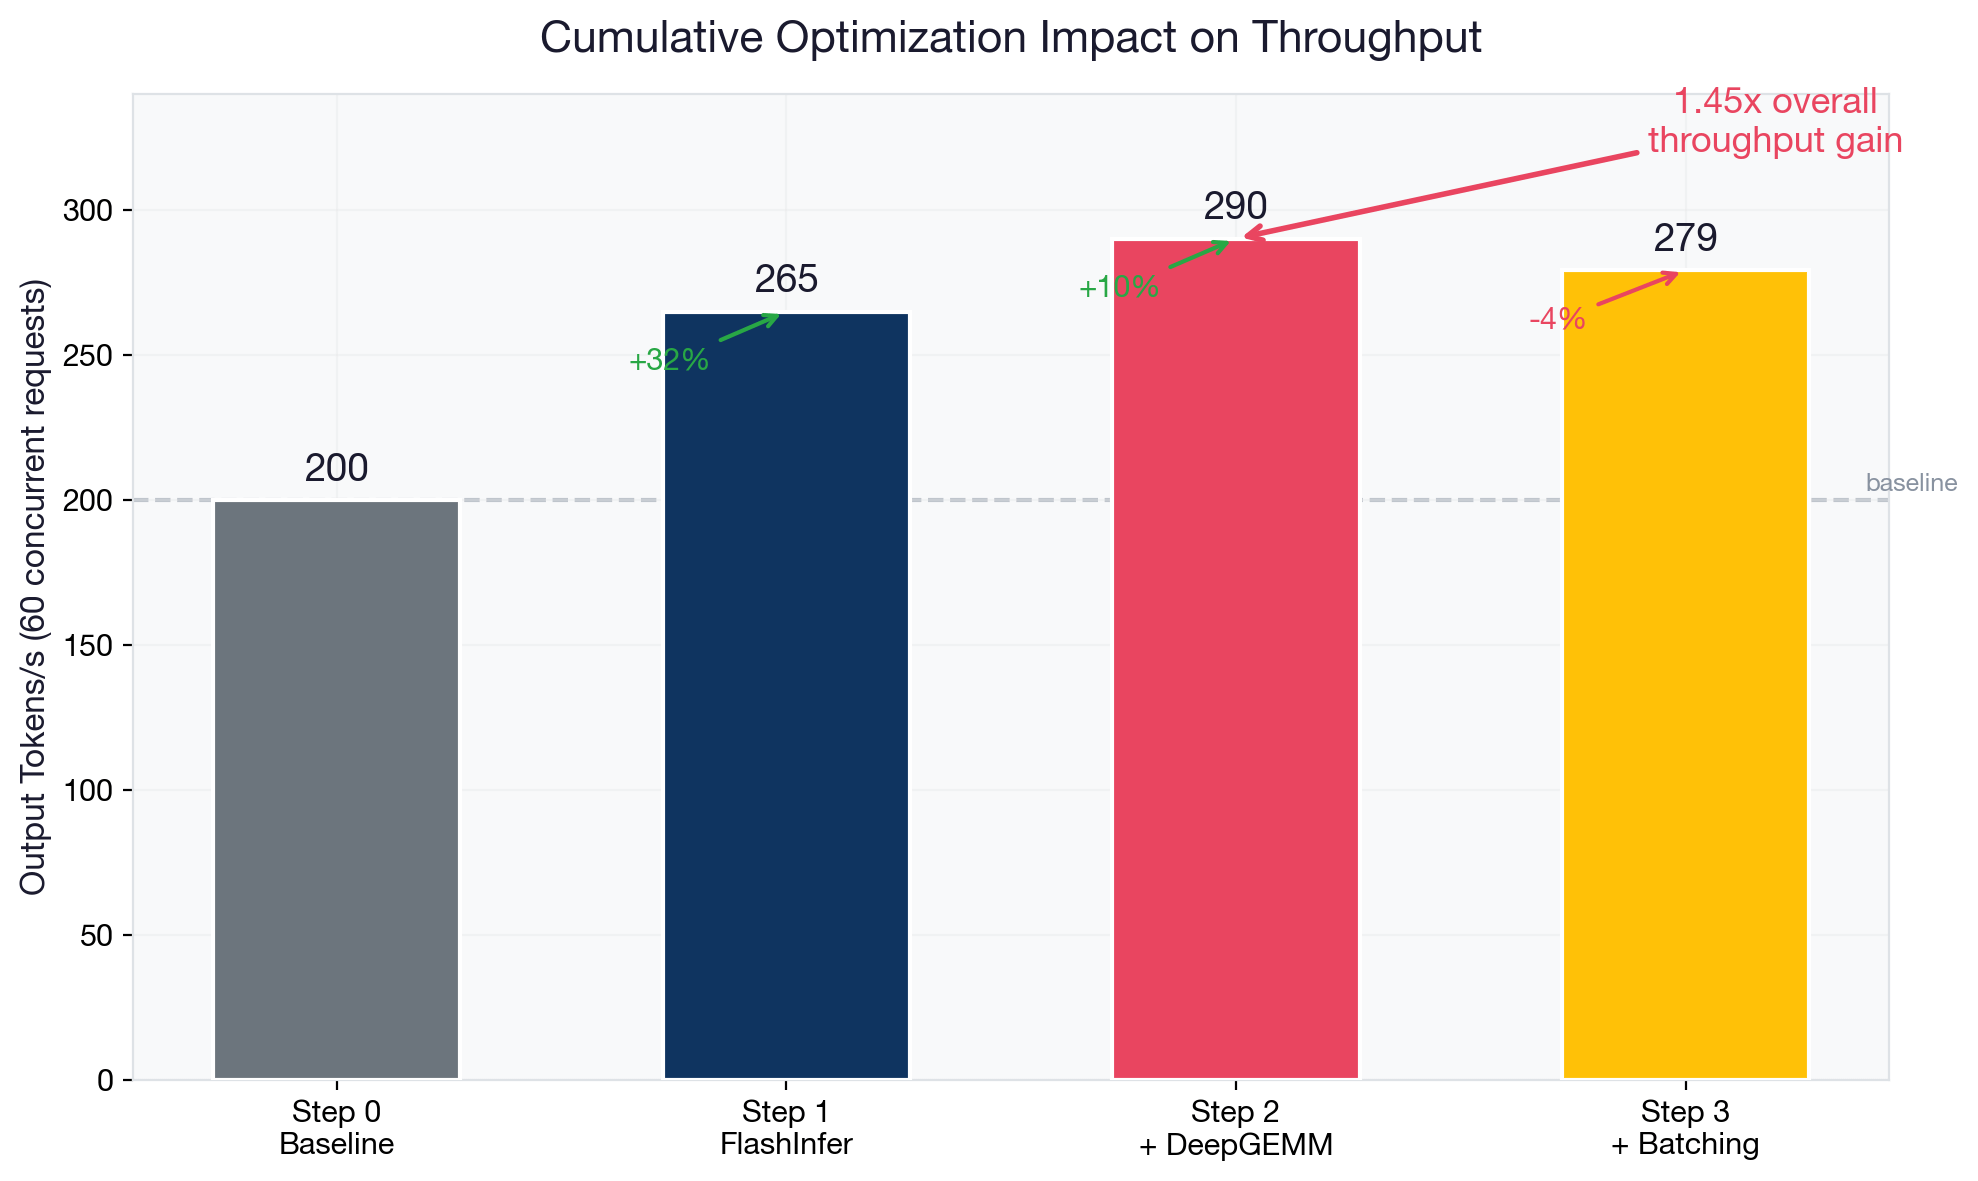
This article documents our optimization journey, the technical reasoning behind each decision, and the benchmark results that guided us.
Test Environment
Hardware: Dell server with 4x NVIDIA H200 GPUs (141 GB HBM3e each), organized in NVLink cluster.
Model: MiniMaxAI/MiniMax-M2.5 (229B parameters, Mixture-of-Experts)
Software: vLLM,
Serving: OpenAI and Anthropic compatible APIs behind an HTTPS reverse proxy
Our Testing Approach
Custom Benchmark Datasets
We created our own purpose-built datasets published at huggingface.co/crozai:
crozai/croz-infbench-sharegpt - Our primary benchmark dataset. Built from the InfiniteBench code_debug split, we replaced the original evaluation prompts with five realistic developer tasks: code refactoring, code review, vulnerability identification, test generation, and bug fixing. The context was trimmed into controlled token buckets (10K, 16K, 32K, 64K, and 96K tokens) with variable expected output lengths. We pre-computed token_count fields for each message to eliminate tokenization overhead from the benchmark client.
crozai/croz-coding-sharegpt - Multi-turn coding conversations “exploded” into single-turn pairs with prior conversation history embedded into the human message, simulating agent session prompts.
Test Scenarios
We designed two complementary test scenarios:
Scenario 1 - Backend and Kernel Optimization tested four progressively optimized vLLM configurations, each measured with:
A single 150K-token sequence (sonnet dataset) to establish baseline per-token latency
60 concurrent requests sampled from our coding dataset (max concurrency 20, fixed seed for reproducibility)
Scenario 2 - Batching Configuration tested three different batching strategies using 20 large prompts (50K+ tokens each), each repeated 3 times to simulate prefix cache reuse patterns typical of developer sessions.
The Model: MiniMax-M2.5 and its MoE Architecture
MiniMax-M2.5 is a 229-billion parameter Mixture-of-Experts (MoE) model. Unlike dense models, where every parameter participates in every token’s computation, MoE models activate only a fraction of their total parameters per token. A routing mechanism selects the top-K experts from a larger pool for each token, achieving the representational capacity of a massive model at a fraction of the computational cost.
Every optimization decision we made was shaped by how MoE models divide their compute between two fundamentally different types of operations.
Understanding the Compute Stack: Attention Backends and GEMM Kernels
A transformer forward pass contains two types of heavy computation, each requiring different optimization strategies:
Attention: FlashAttention vs FlashInfer
Self-attention computes
For a 150K-token sequence, the naive attention score matrix would contain 22.5 billion elements, which is far too large for GPU memory. Specialized attention kernels solve this through tiling: processing the attention computation in blocks that fit in GPU SRAM, never materializing the full N x N matrix.
FlashAttention is the default backend on Hopper-architecture GPUs. It’s a CUDA kernel that processes attention tile-by-tile.
FlashInfer backend takes a different approach. FlashInfer is an attention framework for composing and JIT-compiling specialized kernels at runtime. Designed specifically for the serving use case, it brings several advantages:
Ragged tensors: No padding waste when batching requests of different lengths. Each request occupies exactly the tokens it needs.
Native PagedKV support: vLLM’s paged KV cache operations are fused directly into the attention kernel, avoiding separate memory copies.
StreamK-style load balancing: Work is distributed evenly across streaming multiprocessors, even when request lengths vary dramatically, achieving better memory bandwidth utilization.
FlashInfer also provides MoE GEMM kernels.
GEMM: The Bulk of Compute
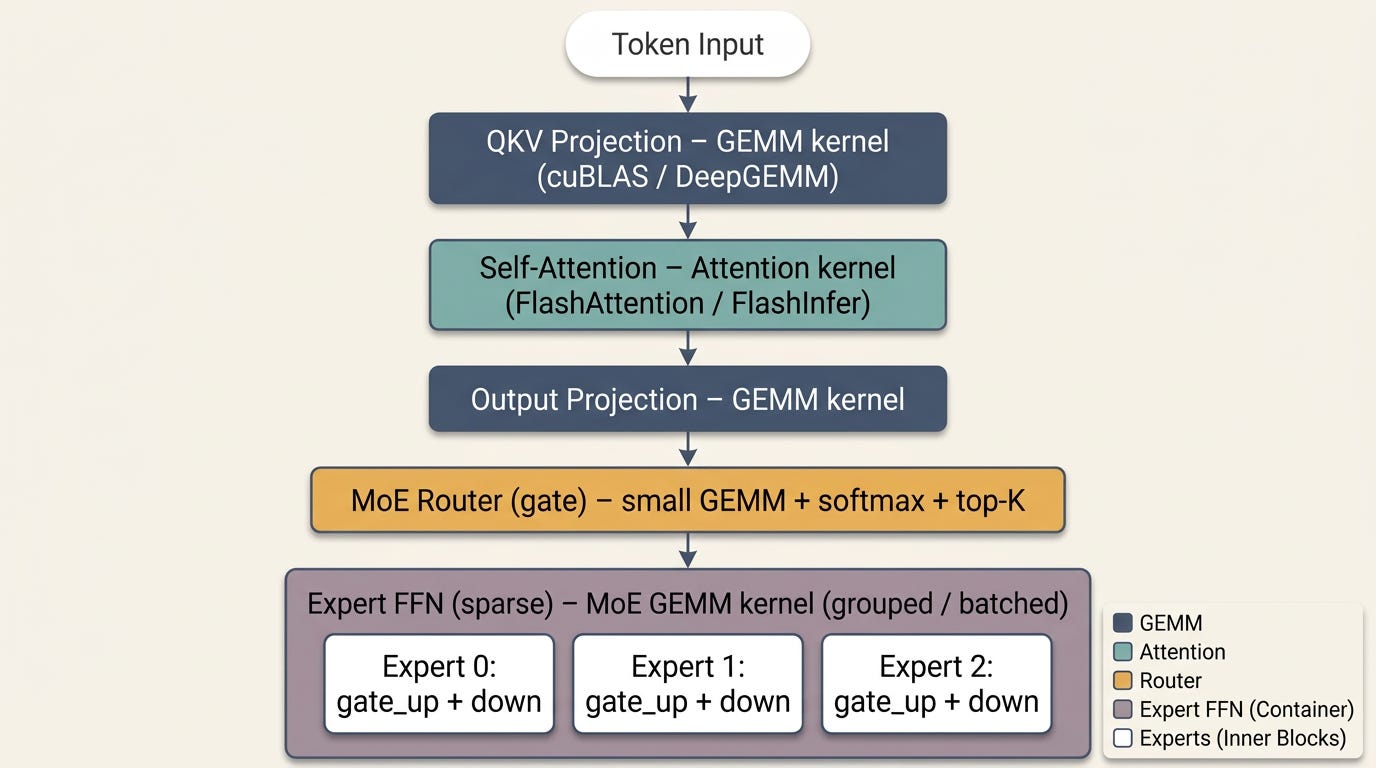
Every operation other than attention is dispatched to a GEMM kernel (General Matrix Multiply): QKV projections, output projections, feed-forward networks, and in MoE models, the expert layers. Attention cannot be dispatched this way because the softmax reduction between its two matrix multiplications creates an N×N intermediate that would exhaust GPU memory at long contexts. Instead, specialized attention kernels solve this algorithmically.
Here’s the architecture of a single transformer layer:
Why Dense and MoE Layers Need Different GEMM Kernels
This is the key architectural insight that drove our optimization strategy.
Dense layer GEMMs (QKV projections, output projections) are standard large matrix multiplications: [batch_tokens x hidden] @ [hidden x output_dim]. The batch dimension M can be large, and the weight dimensions are fixed and large. This is the shape that cuBLAS and DeepGEMM are optimized for.
MoE expert layer GEMMs are fundamentally different. After routing, each expert receives a different number of tokens:
Expert 0: receives tokens [t3, t17, t42]      -> GEMM shape: 3 x K x N
Expert 1: receives tokens [t1, t5]            -> GEMM shape: 2 x K x N
Expert 2: receives tokens [t8, t12, t29, t31] -> GEMM shape: 4 x K x N
...
Expert 31: receives tokens [t7]               -> GEMM shape: 1 x K x N
This creates three problems:
Many small GEMMs instead of one large one - launching separate cuBLAS calls for each expert incurs kernel launch overhead, and each individual GEMM is too small to saturate the GPU.
Variable M per expert - standard GEMM kernels expect fixed dimensions. You need either padding or specialized “grouped GEMM” kernels.
Permutation overhead - tokens must be sorted by expert assignment before the GEMM and unpermuted after, adding latency.
With tensor parallelism across 4 GPUs and expert parallelism, the expert weights are distributed across GPUs. Each expert GEMM on each GPU processes even fewer tokens, making the mismatch with standard GEMM kernels more severe.
DeepGEMM: The Right Tool for the Right Job
DeepGEMM, created by DeepSeek AI, is an FP8 GEMM library that JIT-compiles kernels at runtime. GEMM shapes, block sizes, and pipeline stages become compile-time constants, enabling aggressive register optimization.
DeepGEMM supports both dense and MoE (grouped) GEMM, but the performance advantage narrows for MoE workloads due to the small, irregular matrix shapes. With TP=4 expert parallelism on MiniMax-M2.5, per-GPU expert batch sizes frequently fall below DeepGEMM’s minimum size requirements (M >= 128, N > 512, with N and K aligned to 128), forcing fallbacks. vLLM itself recognizes this problem at TP >= 8, DeepGEMM for MoE is automatically disabled.
This led to our key configuration insight: use different GEMM backends for different layer types. DeepGEMM for dense layers, and FlashInfer CUTLASS throughput mode for MoE expert layers.
Optimization Results: Scenario 1
We tested four progressively optimized configurations.
Step 0: Baseline (Default Settings)
Our starting point was vLLM with default settings: FLASH_ATTN backend, default GEMM selection, and default batching parameters. The only non-default setting was
--max-model-len=192K Step 1: Switching to FlashInfer
Configuration:
VLLM_ATTENTION_BACKEND=FLASHINFER
VLLM_FLASHINFER_MOE_BACKEND=throughput
VLLM_USE_FLASHINFER_MOE_FP16=1
VLLM_USE_FLASHINFER_MOE_FP8=1
This single change replaced both the attention backend and the MoE GEMM backend. FlashInfer’s throughput mode uses the CUTLASS.
Step 2: Optimizing DeepGEMM Placement
Configuration (added to Step 1):
VLLM_USE_DEEP_GEMM=1      # DeepGEMM ON for dense layers
VLLM_MOE_USE_DEEP_GEMM=0  # DeepGEMM OFF for MoE expert layers
With FlashInfer already handling MoE expert GEMMs via VLLM_USE_FLASHINFER_MOE_FP8=1, setting VLLM_MOE_USE_DEEP_GEMM=0 is technically redundant (FlashInfer takes priority in the selection logic), but we included it for explicitness. The key here is ensuring DeepGEMM handles only what it’s best at: the dense linear projections.
Step 3: Increased Batching
Configuration (added to Steps 1-2):
--max-num-batched-tokens=128K
--long-prefill-token-threshold=32768
--max-num-seqs=40
This increases the token budget per scheduler iteration and raises the threshold for classifying a prompt as “long” (which triggers chunked prefill).
Results: Single 150K-Token Sequence
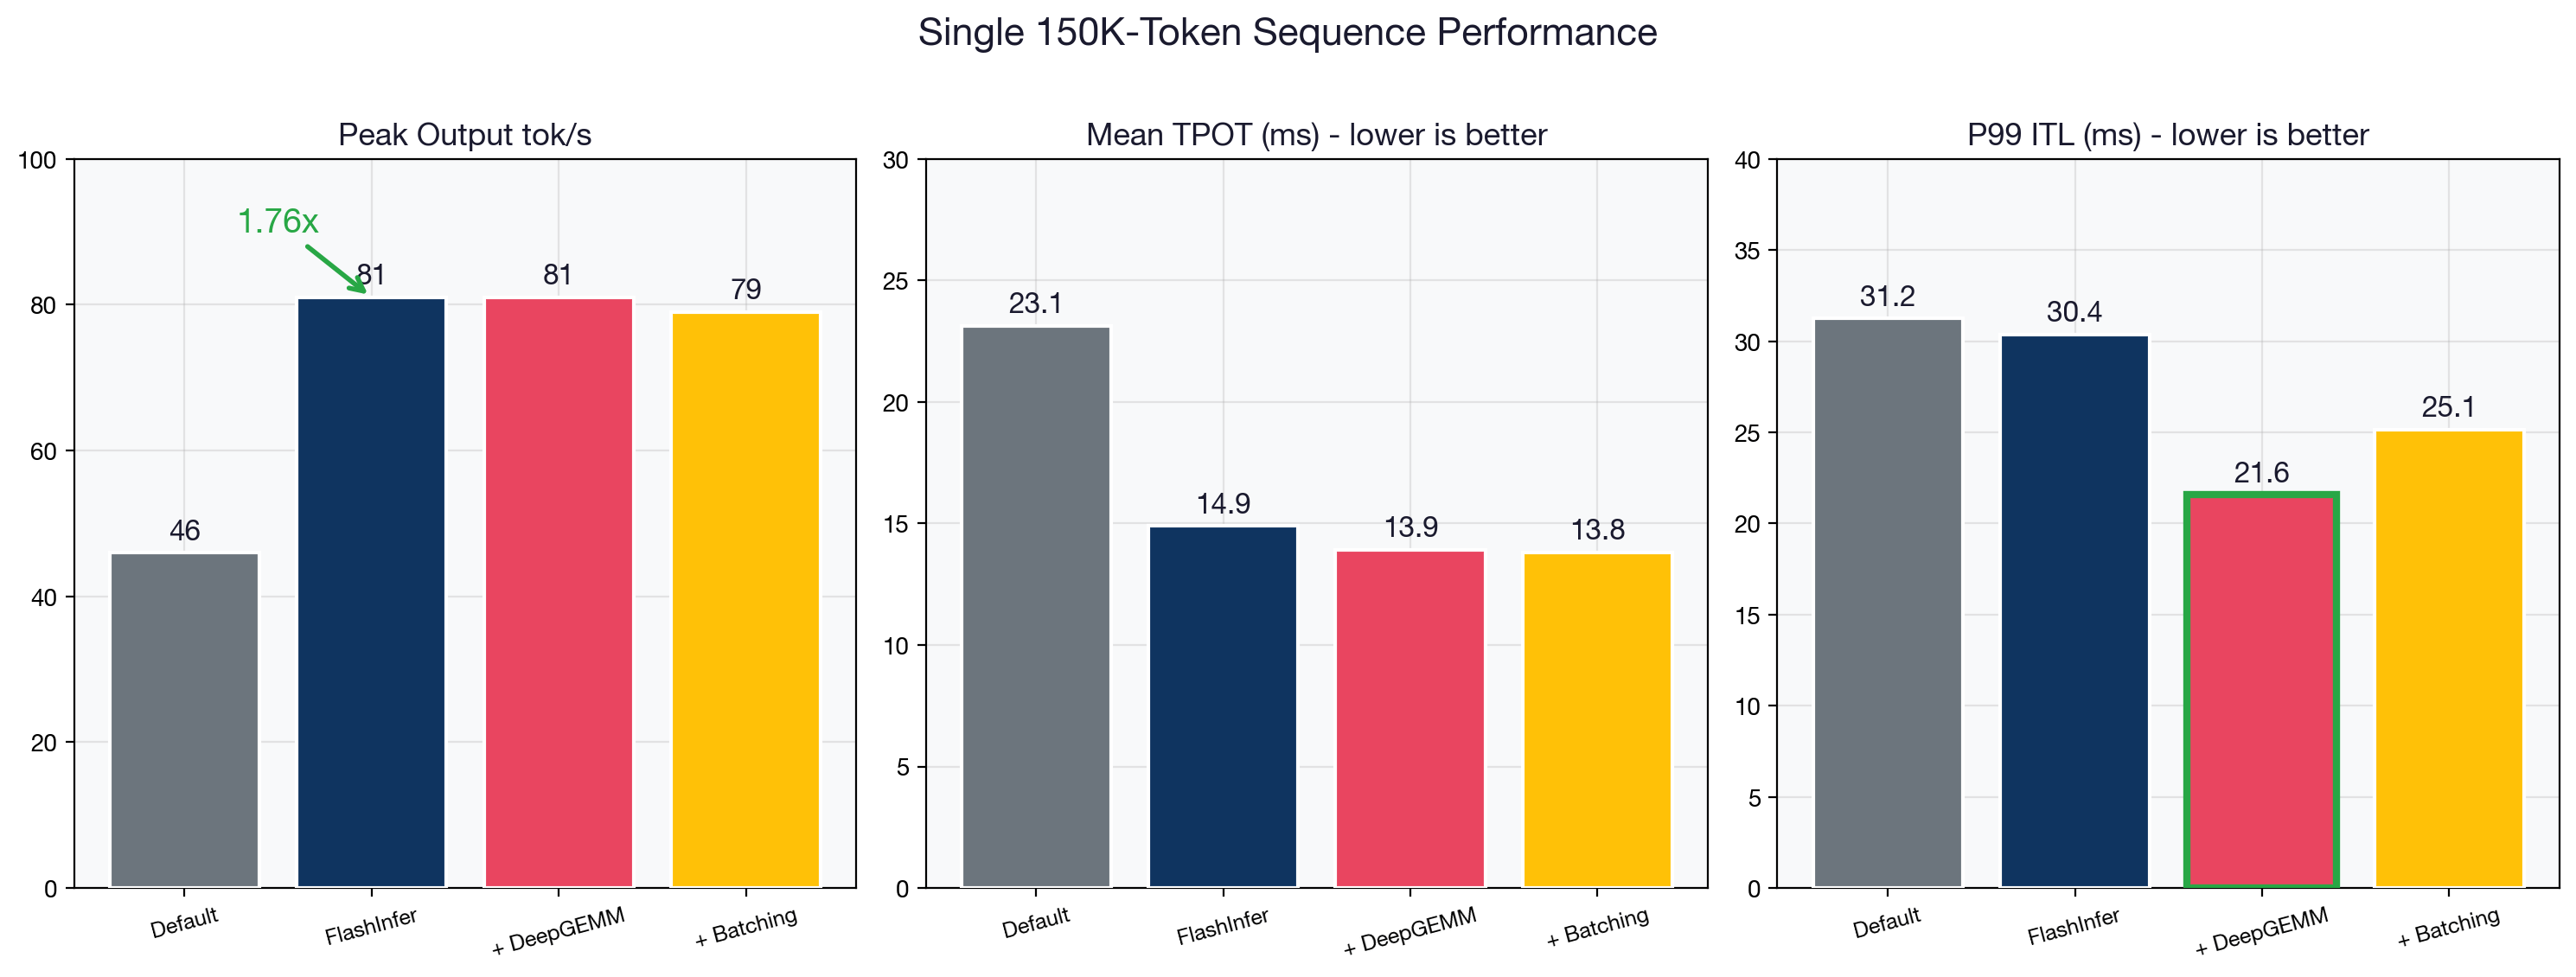
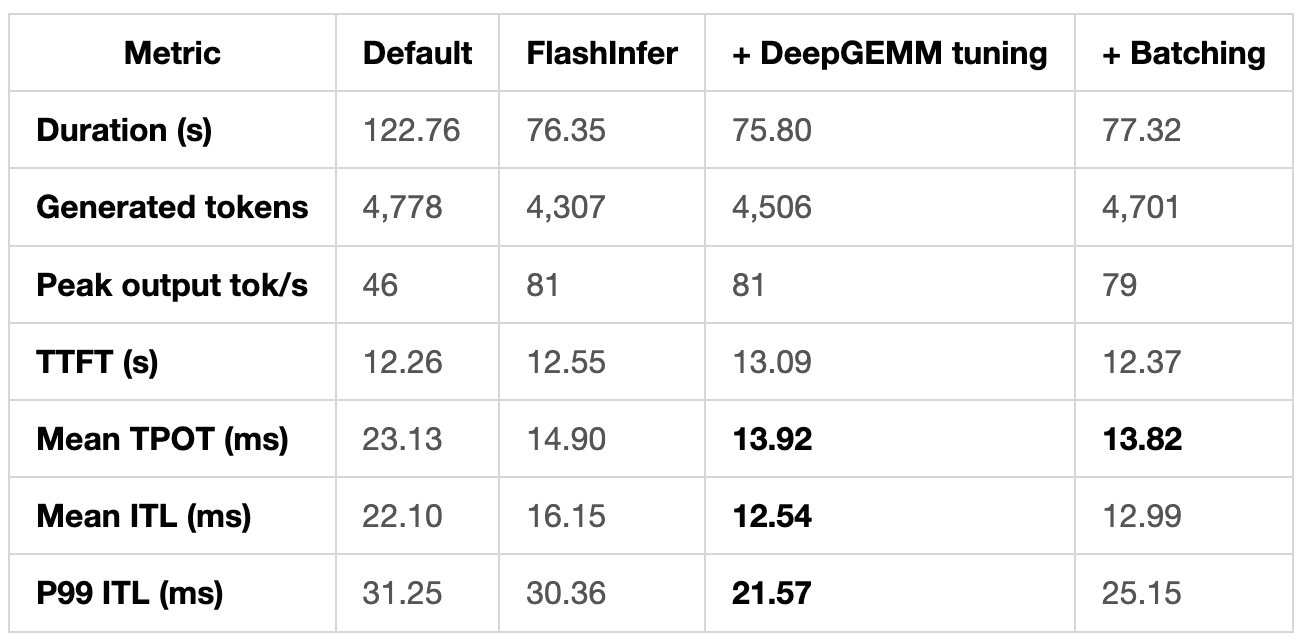
All optimized configurations achieve ~80 tok/s peak generation versus 46 tok/s default, a ~2x speedup. The DeepGEMM tuning provides the best inter-token latency (12.54ms mean, 21.57ms P99). TTFT remains consistent at ~12-13 seconds across all configs, as prefill speed for a single sequence is primarily bound by the 150K tokens of context processing.
Results: 60 Concurrent Requests
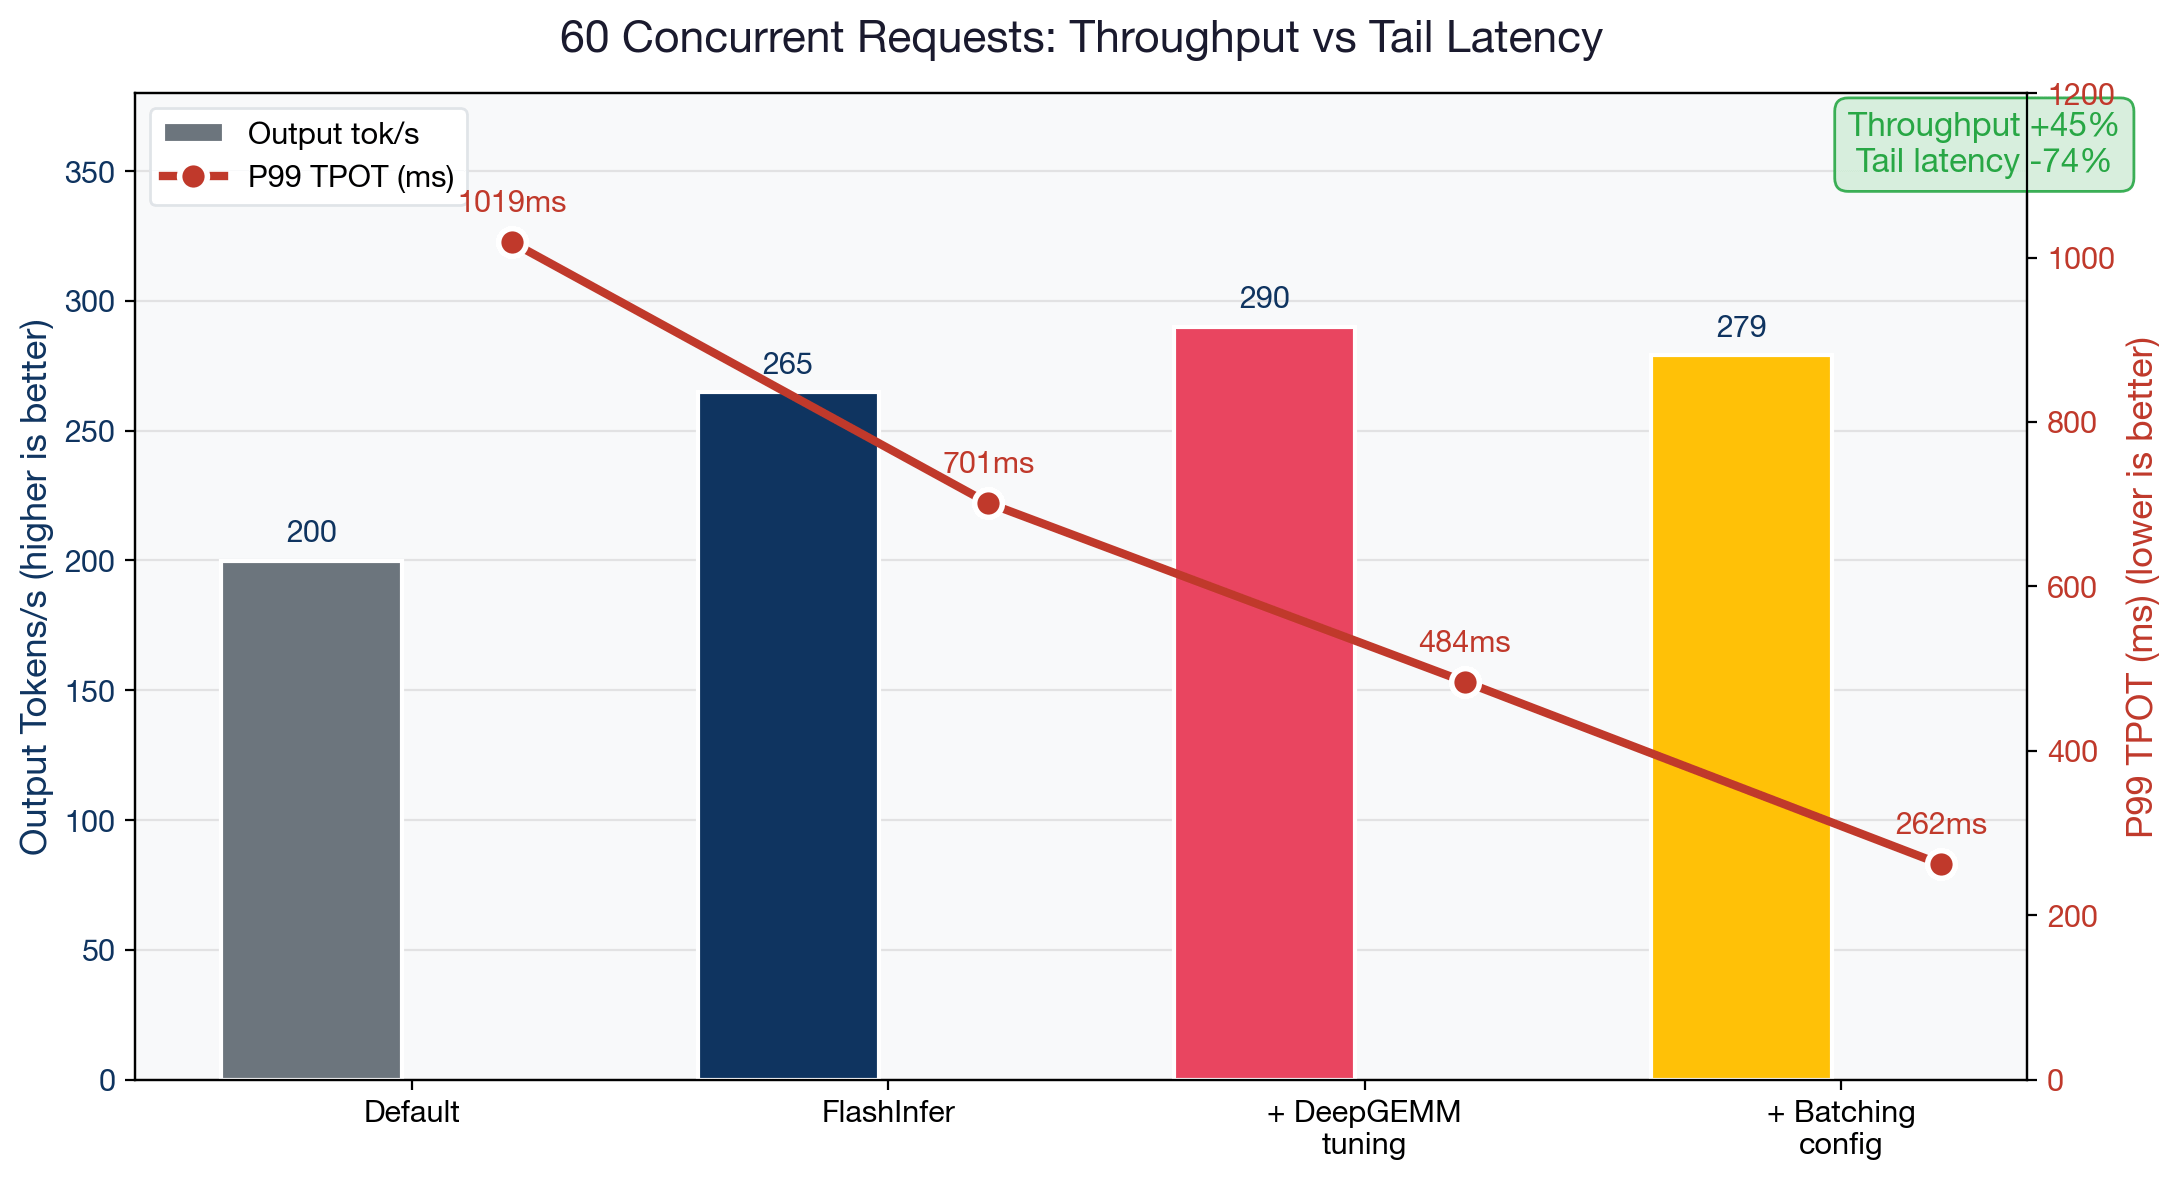
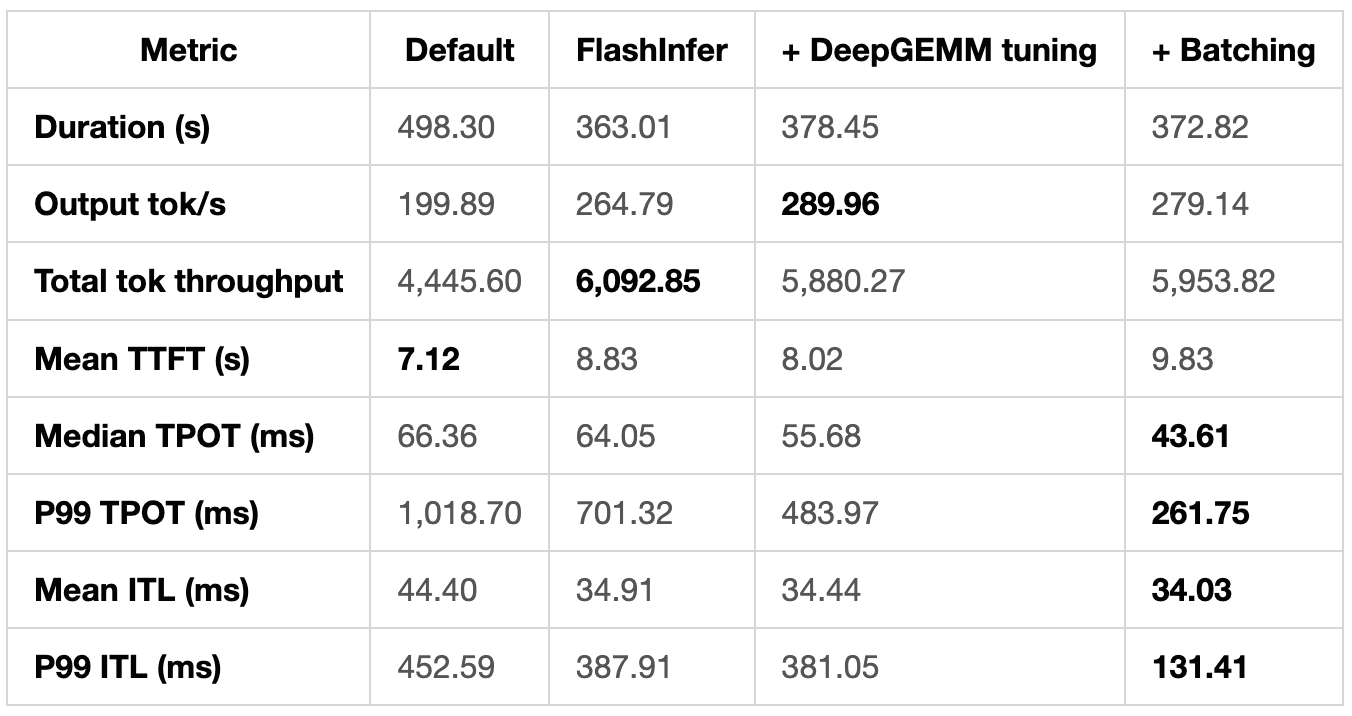
Several clear patterns emerge:
FlashInfer is the single biggest improvement. Switching from FLASH_ATTN to FLASHINFER reduced total benchmark duration by 27% (498s to 363s) and increased total token throughput by 37%. The improvement comes from three factors working together: optimized MoE GEMM kernels, better handling of variable-length batches, and native paged KV cache support that fuses memory operations into the kernel.
DeepGEMM tuning pushes output throughput further. The best output tok/s is 289.96 with DeepGEMM optimally placed, a 45% improvement over default. P99 TPOT drops from 1,019ms to 484ms.
Increased batching improves the tail latency. P99 TPOT drops to 261.75ms (4x better than default), and P99 ITL drops to 131.41ms (3.5x better). For production serving where users expect a constant stream, this matters a lot.
TTFT is the tradeoff. Mean TTFT increases from 7.1s to 9.8s with increased batching, as larger token budgets allow more aggressive prefill batching that can delay individual request starts. However, P99 TTFT actually improves slightly (42.2s vs 44.8s).
Optimization Results: Scenario 2 - Batching Configuration
With our kernel and backend optimizations locked in (FlashInfer + DeepGEMM tuning), we focused on fine-tuning the batching strategy for our specific workload: large developer contexts with high prefix reuse.
Test Design
We sent 20 prompts (all 50K+ tokens) from our coding dataset, each repeated 3 times in sequence, with 20 maximum concurrent requests. The repetition simulates developers iterating on the same codebase context as each subsequent request shares most of the prompt with its predecessors, exercising vLLM’s prefix caching.
Three Configurations
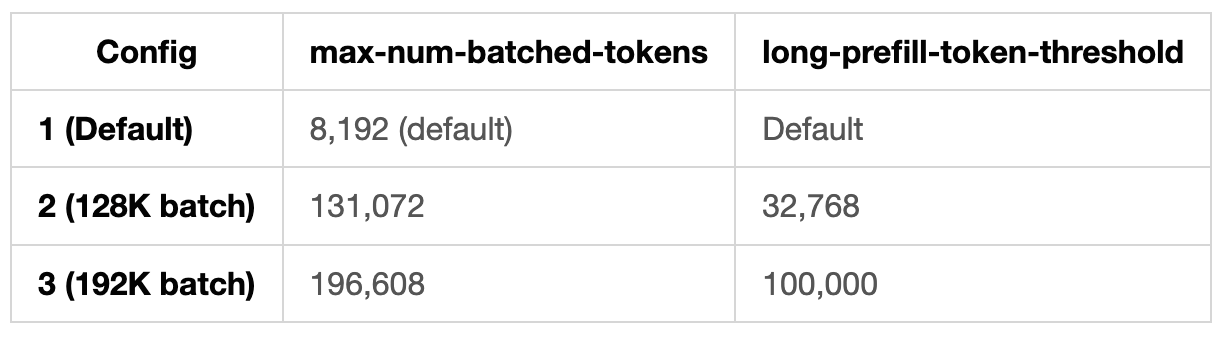
Results
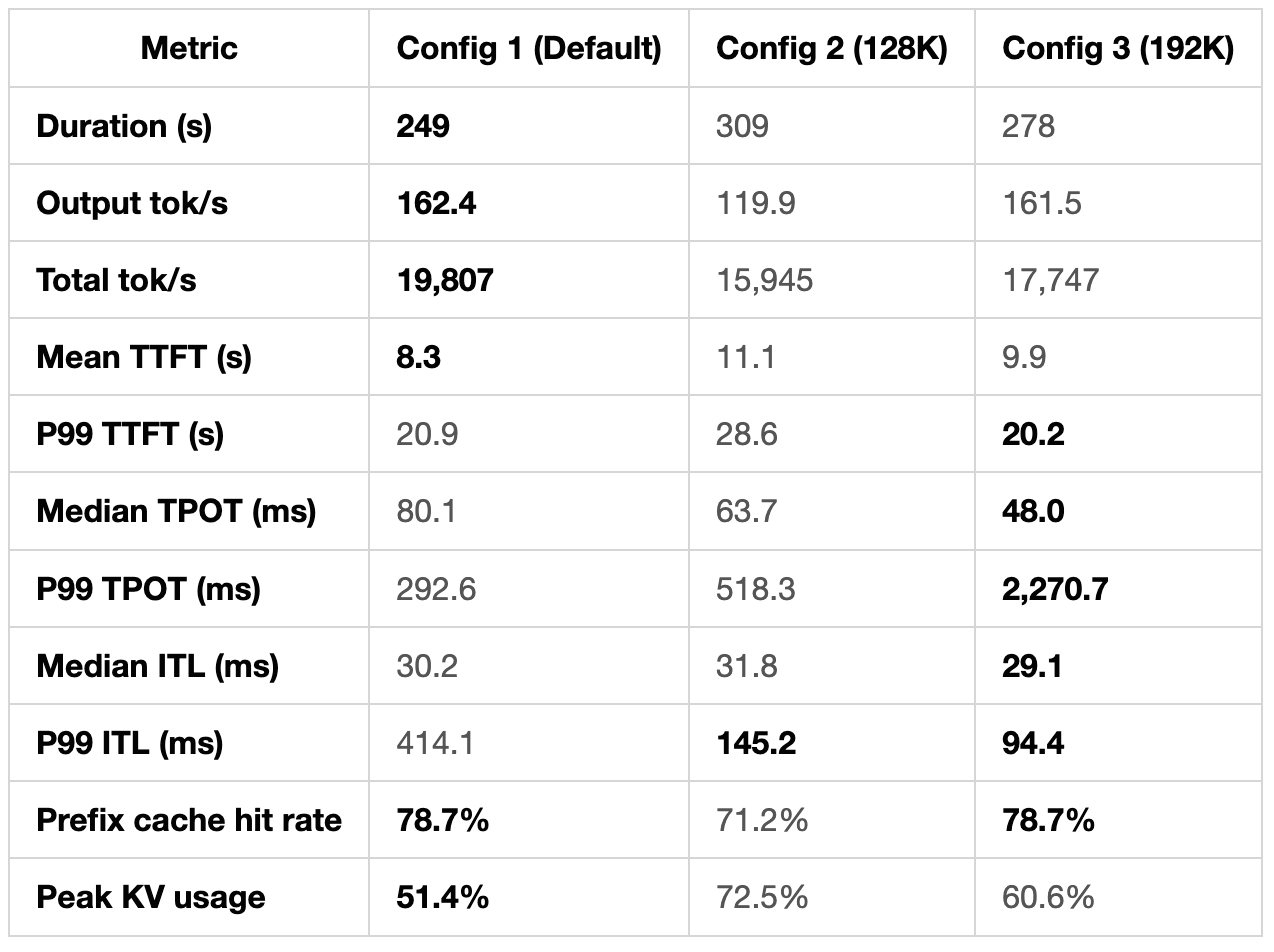
Analysis: The Chunked Prefill Tradeoff
The results reveal a fundamental tradeoff in how chunked prefill interacts with concurrent decode operations.
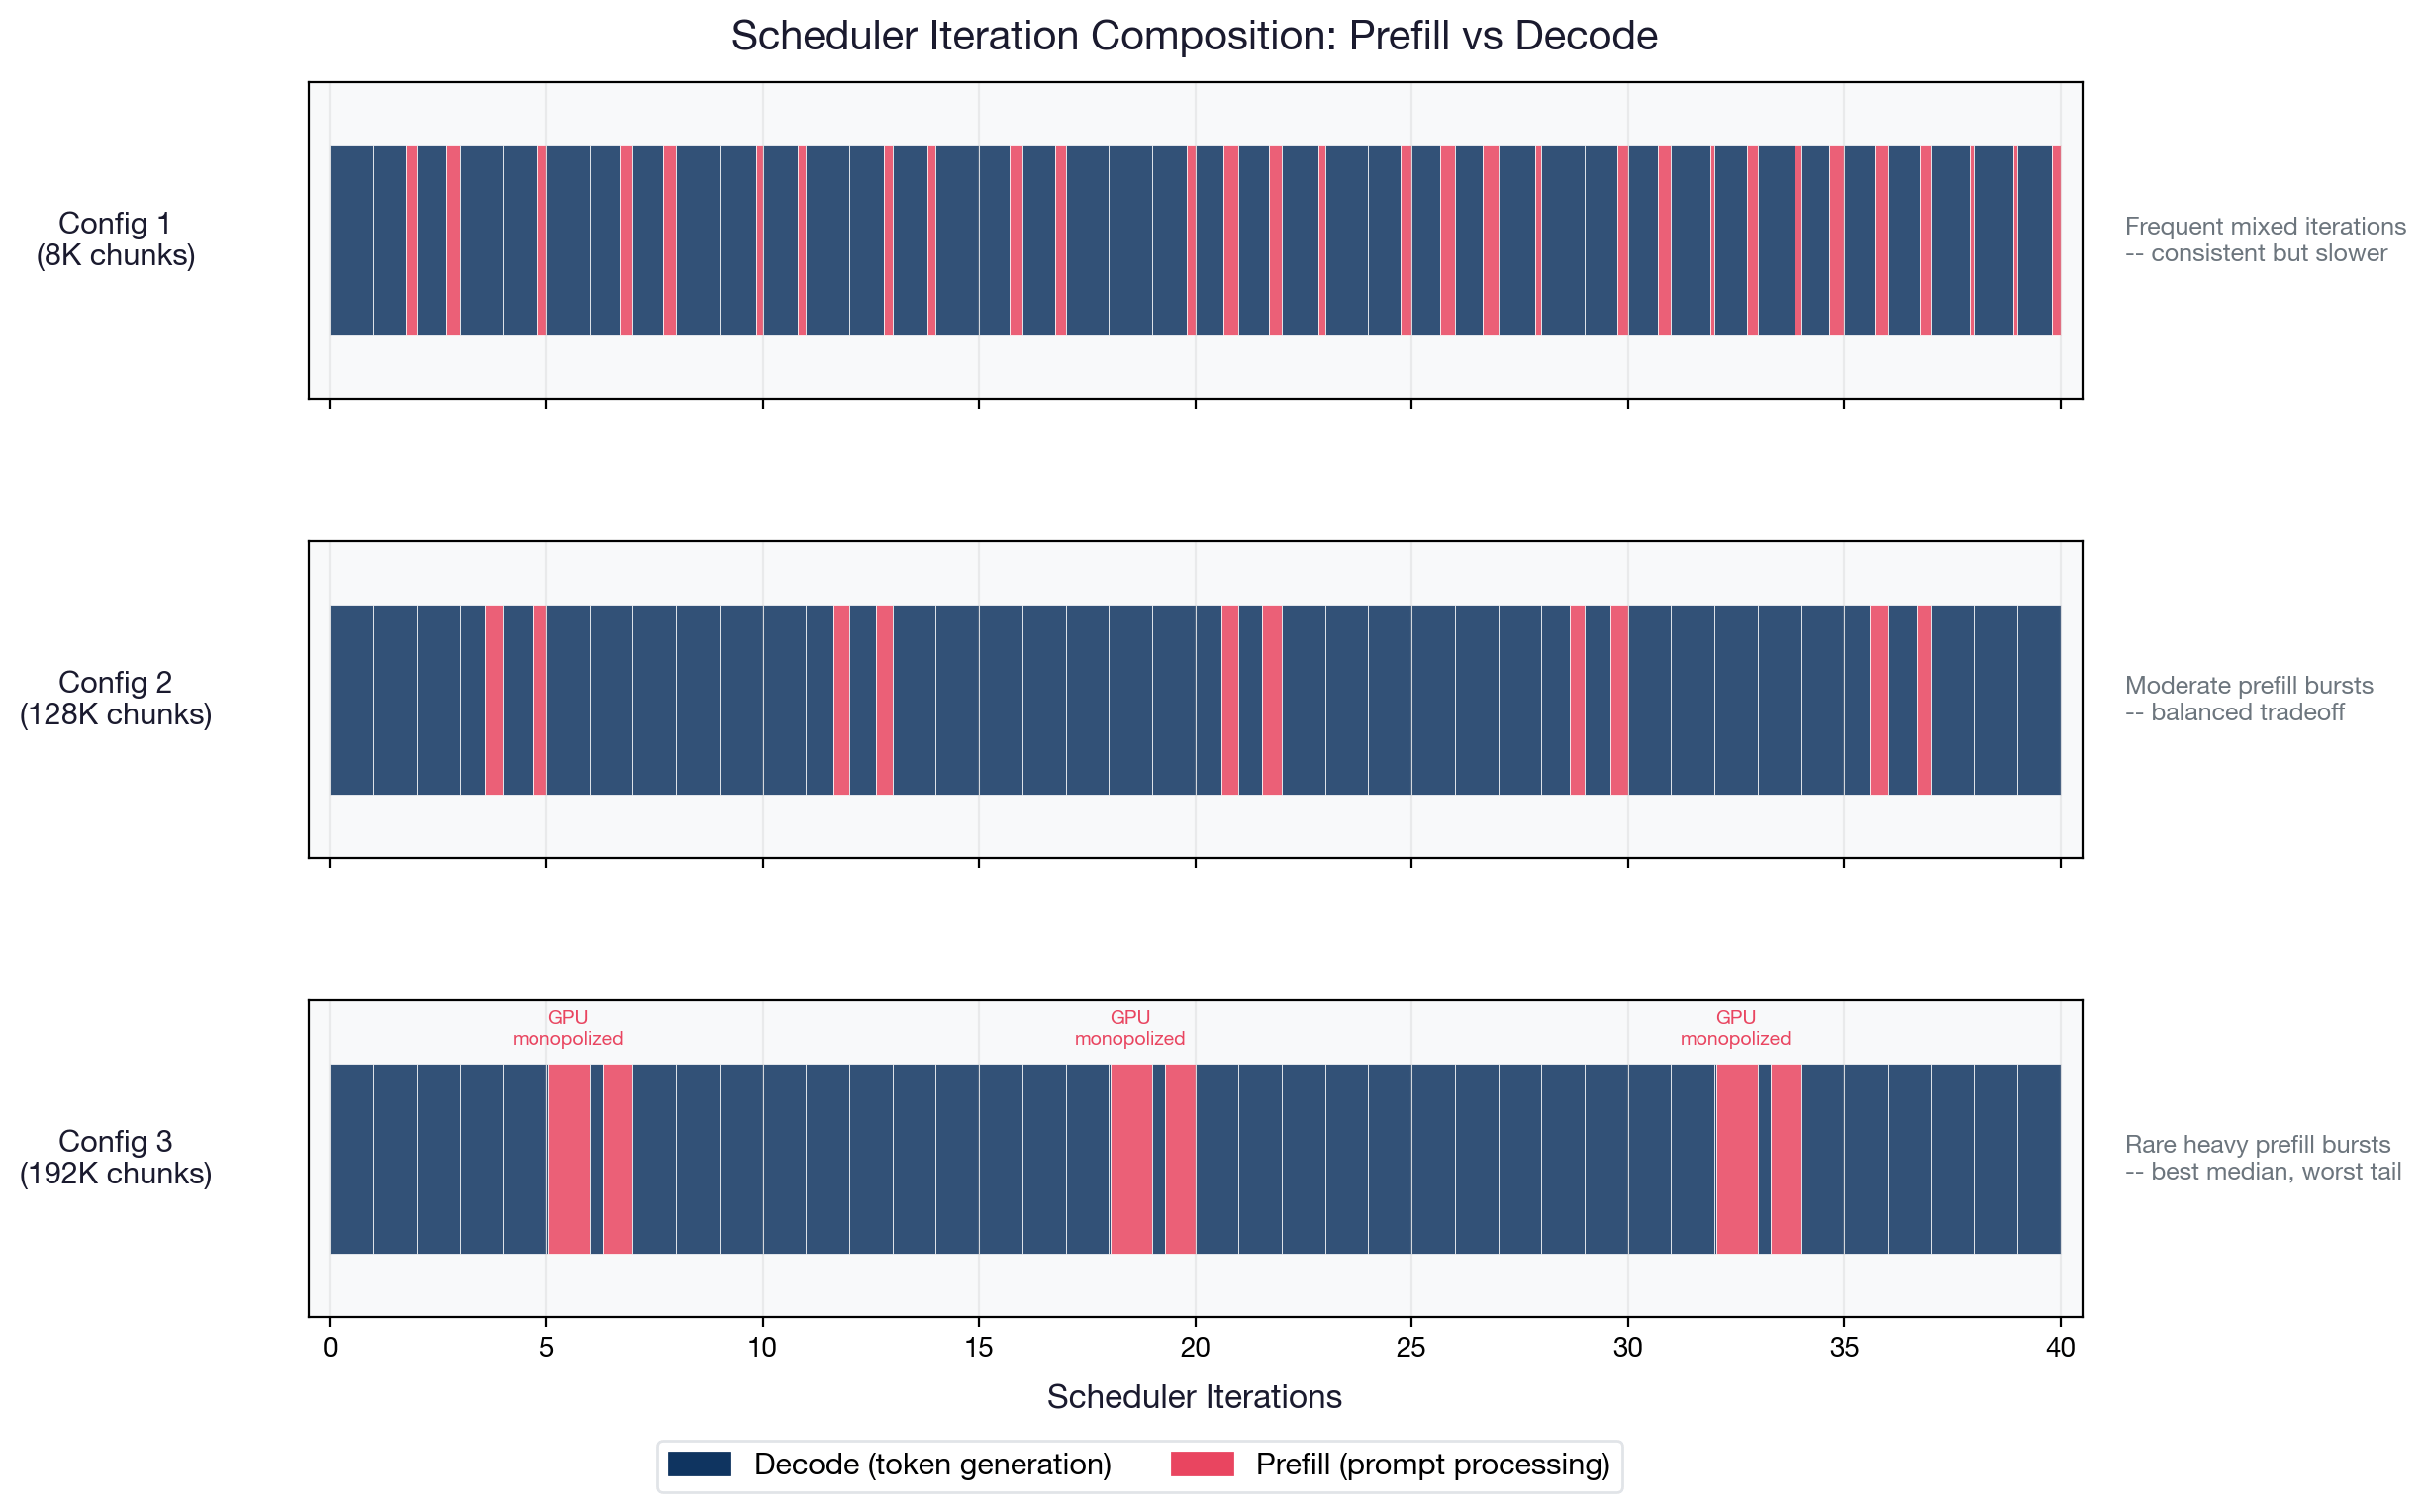
Config 1 (small chunks) splits non-cached prefill into many small chunks across many scheduler iterations. Almost every decode iteration has some prefill mixed in. Every request gets slightly degraded, but no request gets severely stalled. The result: best mean metrics, consistent experience.
Config 3 (large chunks) processes non-cached prefill in a few large chunks. Most decode iterations run with zero prefill interference, producing excellent median TPOT (48ms, nearly half of Config 1’s 80ms). But when a large prefill chunk does fire, it monopolizes the GPU, causing multi-second stalls for concurrent decode requests. This explains the extreme P99 TPOT (2,271ms) despite the excellent median.
Server logs confirm this bimodal pattern:
Config 1 - frequent mixed iterations:
prompt: 22K tok/s, gen: 629 tok/s
prompt: 25K tok/s, gen: 157 tok/s  <- prefill dragging decode down
prompt: 56K tok/s, gen:  36 tok/s  <- decode nearly stalled
Config 3 - long pure decode stretches, brief heavy prefill:
prompt:     0 tok/s, gen: 658 tok/s  <- pure decode
prompt:     0 tok/s, gen: 650 tok/s  <- pure decode
prompt:     0 tok/s, gen: 652 tok/s  <- pure decode
prompt:  9.7K tok/s, gen:   2 tok/s  <- big prefill, decode stalls
Config 2 (128K): The Middle Ground
Config 2 balances the extremes. It avoids Config 1's constant prefill-decode interference while keeping prefill chunks smaller than Config 3's GPU-monopolizing bursts. It delivers better median TPOT than Config 1 (63.7ms vs 80.1ms) and far better P99 TPOT than Config 3 (518ms vs 2,271ms), making it a practical middle-ground choice for teams that want improved per-request latency without severe tail spikes.
Production Recommendations
The optimal configuration depends on the concurrency level. Start with larger batching and reduce as your team grows:
For small teams: (Large batch). At low concurrency, the P99 TPOT tail spikes rarely affect anyone. A large prefill chunk stalls only 1-2 other decode sequences. You get the best median TPOT.
For medium teams: (Medium batch). Good median TPOT without the multi-second tail spikes of Large batch config. A practical balance between per-request speed and latency consistency.
For large teams: (Smaller batches). Latency consistency matters more than peak per-request speed. Every request gets slightly slower, but no request gets severely stalled. At this scale, consider scaling horizontally with multiple replicas and session affinity rather than tuning a single instance.
Model Loading Speed
A separate but significant optimization:
SAFETENSORS_FAST_GPU=1This environment variable enables the safetensors library’s fast GPU loading path, which bypasses CPU-to-GPU copies by memory-mapping model weights directly for GPU transfer. Model loading time dropped from 53 seconds to 13.58 seconds. Almost 4x speedup. For containerized deployments, this substantially improves time-to-readiness.
Final Configuration
Our optimized vLLM configuration for MiniMax-M2.5 on 4xH200:
# Environment variables
VLLM_ATTENTION_BACKEND=FLASHINFER         # FlashInfer for attention
VLLM_USE_FLASHINFER_MOE_FP8=1             # FlashInfer for FP8 MoE experts
VLLM_USE_FLASHINFER_MOE_FP16=1            # FlashInfer for FP16 MoE experts
VLLM_FLASHINFER_MOE_BACKEND=throughput    # CUTLASS pathway, throughput-optimized
VLLM_USE_DEEP_GEMM=1                      # DeepGEMM for dense linear layers
VLLM_MOE_USE_DEEP_GEMM=0                  # Disable DeepGEMM for MoE experts
SAFETENSORS_FAST_GPU=1                    # Fast model loading

# vLLM engine args
--gpu-memory-utilization=0.95
--tensor-parallel-size=4
--enable-expert-parallel
--model=MiniMaxAI/MiniMax-M2.5
--max-model-len=192K
--max-num-batched-tokens=64000
--long-prefill-token-threshold=6000
--max-num-seqs=60
Batching parameters (--max-num-batched-tokens, --long-prefill-token-threshold) should be tuned based on expected concurrency, as discussed above.
One additional remark. Our tests were performed with vLLM 0.14, and the upper configuration is for that version. The latest vLLM configuration uses args instead of env variables, and an equivalent configuration for the latest vLLM would be:
# vLLM engine args
--gpu-memory-utilization=0.95
--tensor-parallel-size=4
--enable-expert-parallel
--model=MiniMaxAI/MiniMax-M2.5
--max-model-len=192K
--max-num-batched-tokens=64000
--long-prefill-token-threshold=6000
--max-num-seqs=60
--attention-backend FLASHINFER
--moe-backend flashinfer_cutlass
--load-format fastsafetensors
Key Takeaways
MoE models require separate optimization for dense and expert layers.
FlashInfer’s serving-oriented design delivers compound benefits.
Batching configuration is a tradeoff, not an optimization.
Prefix cache hit rate is the metric that rules all others.
Model loading time is a deployment concern worth optimizing.
Custom benchmark datasets aligned with your actual workload.
The benchmark datasets used in this study are publicly available at huggingface.co/crozai. The MiniMax-M2.5 model is available at huggingface.co/MiniMaxAI/MiniMax-M2.5.